Green Across the Board, Dark Across the Ocean: Why Your Uptime Metrics May Be Lying to You
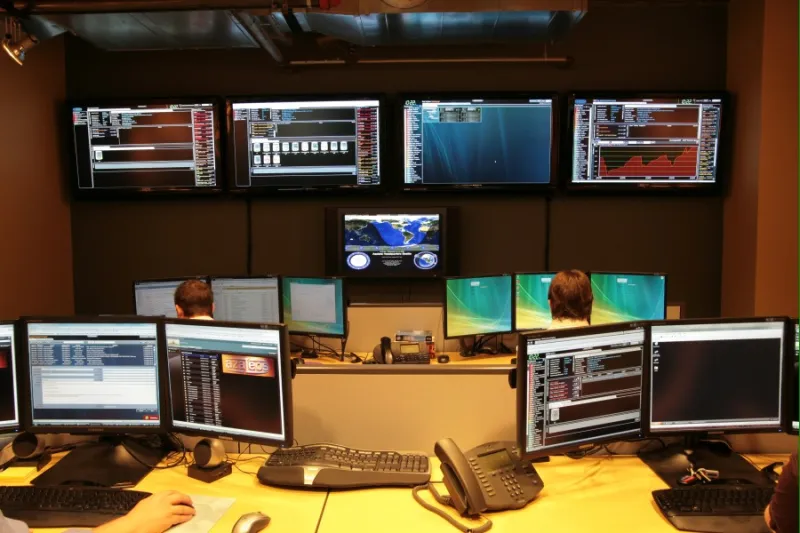
Photo: Azaleos, CC BY-SA 3.0, via Wikimedia Commons
The incident report read like a success story. Ninety-nine point nine seven percent availability, zero flagged anomalies, all monitoring checks passing. Yet for eleven hours, customers in São Paulo, Frankfurt, and Singapore could not complete a single transaction. The dashboard never turned red because, from where the monitoring ran, nothing was wrong.
This scenario plays out in American enterprises every week, and it persists because of a structural blind spot: the majority of US companies still measure uptime from a single region, usually wherever headquarters happens to be. The result is an availability metric that describes the experience of one office, not the experience of the customer base.
The Vantage Point Problem
Monitoring tools answer only the question they are asked. When probes run from a Virginia data center, they measure whether a Virginia-based request can reach the application. They say nothing about whether a customer in Jakarta, routing through different undersea cables, peering arrangements, and regional edge nodes, can do the same.
The gap between those two realities widens with every layer of the delivery stack. Content delivery networks, regional load balancers, DNS geolocation, and third-party API dependencies can each fail independently for one geography while remaining healthy everywhere else. A misconfigured CDN rule in Europe, a saturated transit link in the Asia-Pacific region, or a failed regional DNS resolver can black out an entire market invisibly.
Worse, some failures are self-inflicted. Consider a common pattern: a US retailer pushes a firmware update or a certificate rotation overnight, validates it from headquarters, and moves on. The change breaks connectivity for a single regional gateway. The validation checks pass. The affected customers, thousands of miles away, simply stop buying.
What Single-Region Monitoring Misses
The failure modes that escape single-vantage-point observability share a signature: they are geography-bound.
- Regional CDN or edge failures that degrade page loads or break checkout flows in one continent only
- DNS geolocation errors that route international users to unreachable or wildly distant endpoints
- Cross-border packet loss on specific submarine cable routes, invisible to domestic probes
- Region-specific third-party outages, such as a payment gateway or identity provider failing only in one market
- Regulatory or routing changes, like a country-level block or a carrier-level misconfiguration
In each case, the aggregate uptime number looks respectable while a meaningful slice of revenue quietly disappears. For a company deriving 30 or 40 percent of sales from international markets, a sustained regional outage can erase more margin in a quarter than a headline-grabbing domestic outage ever would.
A Framework for Multi-Region Observability
Closing the gap does not require replacing existing tooling. It requires repositioning where the questions get asked. A practical framework has four layers.
1. Distribute the probes. Synthetic monitoring agents should run from every region where customers exist, not just where servers exist. Most major observability platforms support this today; the work is in configuring and prioritizing it, not buying it.
2. Measure the customer journey, not the endpoint. A server responding in 80 milliseconds tells you little if the checkout fails at the payment step. Synthetic transactions should walk the full path a real customer walks: load, authenticate, add to cart, pay. Segment those journeys by region and alert on regional divergence.
3. Establish per-region baselines and error budgets. A single global SLA number hides regional variance. Set independent availability and latency targets per market, and treat a breach in any one of them with the same urgency as a global one.
4. Tie regional signals to business metrics. Conversion rate, cart abandonment, and support ticket volume should be charted alongside technical telemetry. When regional conversion drops and synthetic journeys fail simultaneously, the incident is real even if the primary dashboard disagrees.
Making Regional Health a Governance Issue
Technology alone will not fix this if organizational incentives do not change. Many enterprises discover their observability gaps only after an international incident, when someone asks why nobody knew. The answer is usually that nobody was assigned to know.
Enterprises that get this right treat regional availability as a board-level reliability metric, alongside financial reporting. Each market has a named owner. Each region has its own error budget and escalation path. Executive dashboards show a matrix of health, not a single averaged number that flatters everyone.
The uptime dashboard is not lying, exactly. It is answering a narrower question than most leaders assume. The enterprises that win globally are the ones who insist on asking the fuller question: not "is the system up?" but "is the system up for every customer, everywhere we've promised to serve them?"
That distinction, repeated across hundreds of operational decisions, is what separates a global operation from a domestic one with international customers attached.